The best model for the job, every time.
The lead changes hands every few weeks. Instead of betting the company on one lab, give your teams OpenAI, Anthropic, Google, xAI, Mistral and leading open-weight models in one place, with one login, one prompt library and one set of rules.
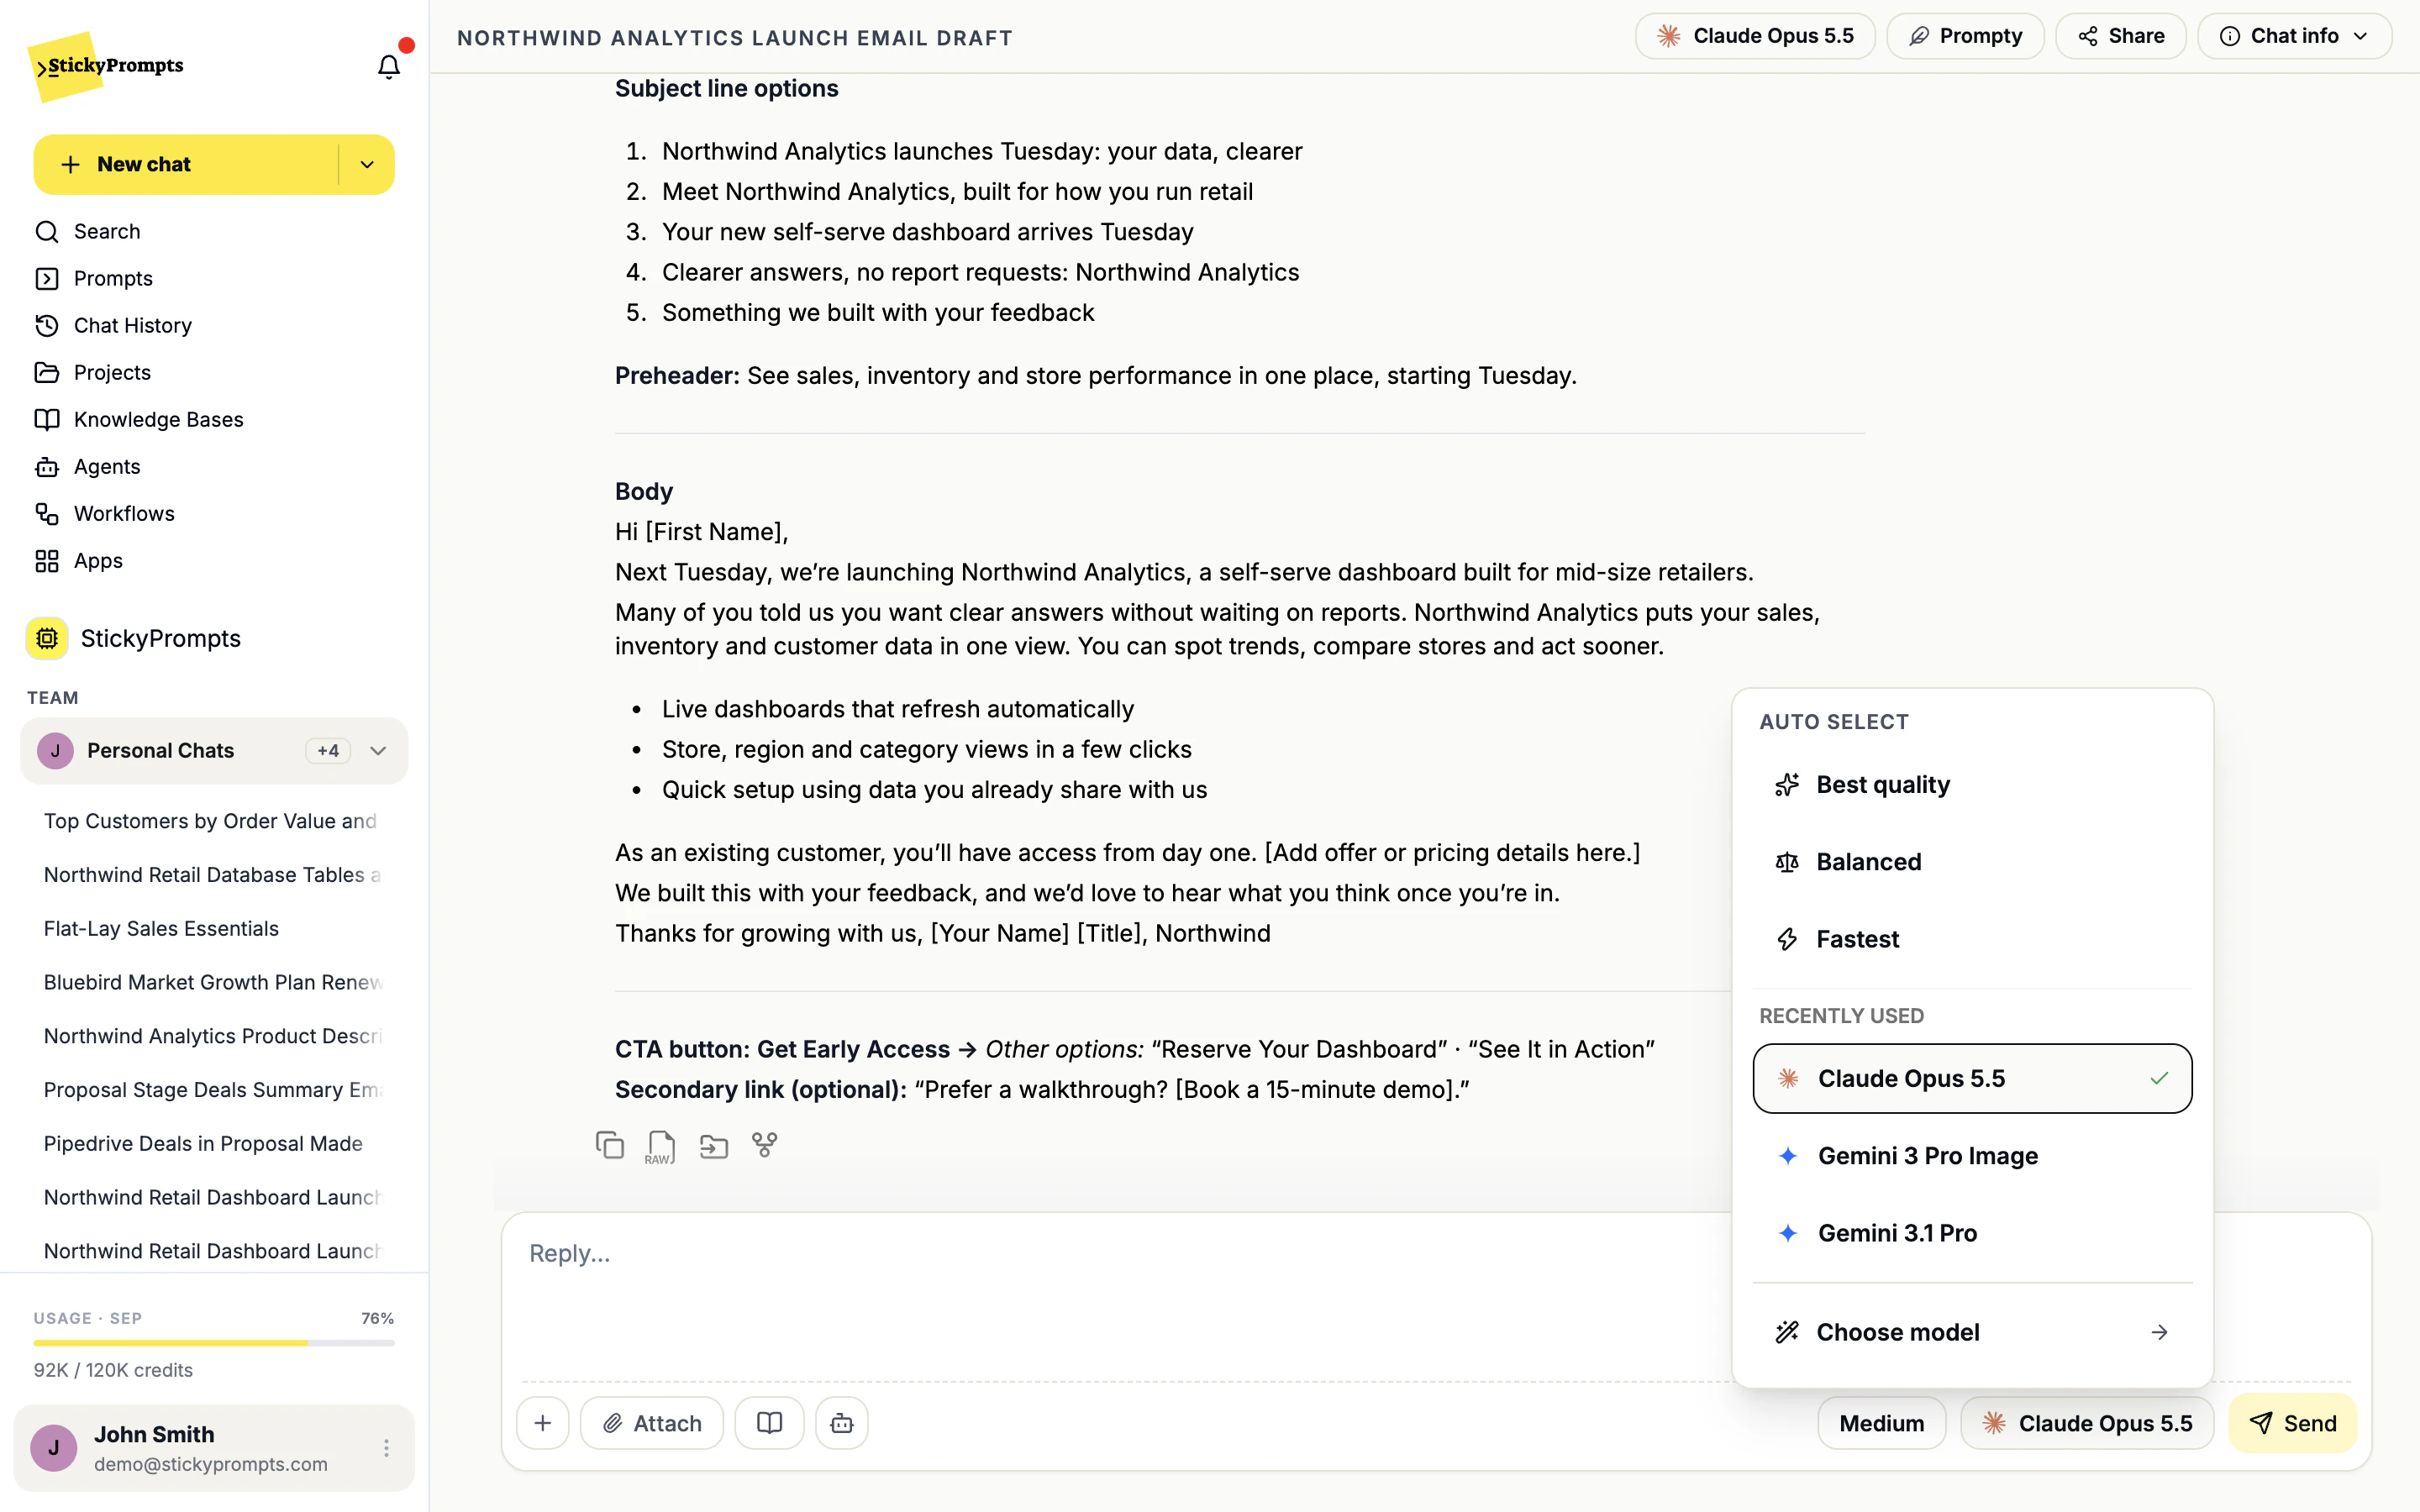
Three kinds of model, one place to use them.
A selection of what is in the model picker today. The full list is longer and changes as providers ship, which is exactly why it pays not to build on a single one.
Frontier
The strongest models from OpenAI, Anthropic and Google. Reach for these when the answer has to be right the first time.
- GPT-6 AstraOpenAIGPT-6 AstraGPT-6 Astra is OpenAI's flagship model for demanding end-to-end work.1.05M context · $10/$50 per 1M Frontier reasoning
- Claude Opus 5.5AnthropicClaude Opus 5.5Claude Opus 5.5 is Anthropic's flagship model for demanding reasoning, coding, and long-horizon agentic work, succeeding Claude Opus 5.1M context · $4/$20 per 1M Long documents & code
- Gemini 3.1 ProGoogleGemini 3.1 Pro PreviewNearest catalogue entry for "Gemini 3.1 Pro"Gemini 3.1 Pro Preview is Google’s frontier reasoning model, delivering enhanced software engineering performance, improved agentic reliability, and more efficient token usage across complex workflows.1.05M context · $2/$12 per 1M Multimodal reasoning
- Claude Fable 5.1AnthropicClaude Fable 5.1Claude Fable 5.1 improves on Claude Fable 5 across the board, with the biggest gains in agentic coding, long-running agentic workflows, and knowledge work: long code refactors, front-end and visual...1M context · $10/$50 per 1M Agentic coding
- Gemini 3.8 FlashGoogleGemini 3.8 FlashGemini 3.8 Flash is Google's most intelligent Flash model with significant gains from 3.7 Flash across software engineering, agentic tasks, and multi-step reasoning.1.05M context · $0.75/$3.75 per 1M Fast · 1M context
- Claude Sonnet 5.5AnthropicClaude Sonnet 5.5Claude Sonnet 5.5 is Anthropic's Sonnet-class model for well-scoped everyday work, succeeding Claude Sonnet 5 as a direct upgrade.1M context · $2/$10 per 1M Everyday work
- GPT-6 SolOpenAIGPT-6 SolGPT-6 Sol is the cost-efficient high-end model in OpenAI's GPT-6 series, positioned below the flagship GPT-6 Astra and above the fast GPT-6 Luna tier.1.05M context · $2/$10 per 1M Balanced
Open-weight
Open models that StickyPrompts runs itself rather than sending your request to the lab that published them. Strong, and a shorter path for your data.
- Kimi K3Moonshot AIKimi K3Kimi K3 is a 2.8T parameter open-weight multimodal reasoning model from Moonshot AI.1.05M context · $3/$15 per 1M Open weights
- DeepSeek V4 Pro Open weights
- GLM 5.2Z.aiGLM 5.2GLM 5.2 is a large-scale reasoning model from Z.ai.1.05M context · $0.325/$4.4 per 1M Open weights
- Qwen3.7 MaxAlibaba (Qwen)Qwen3.7 MaxQwen3.7-Max is the flagship model in Alibaba's Qwen3.7 series.1M context · $1.48/$4.43 per 1M Open weights
- GPT-OSS 120b Open weights
- MiniMax M3MiniMaxMiniMax M3MiniMax-M3 is a multimodal foundation model from MiniMax.1.05M context · $0.3/$1.2 per 1M Open weights

Image, video & audio
Generation sits in the same workspace, under the same policies and the same usage record. It is not a separate tool somebody signs up for on the side.
- Veo 3.1Video generationVeo 3.1Generation models are metered exactly like chat, and sit under the same model allow-lists and audit log. Video
- Seedance 2.5Video generationSeedance 2.5Generation models are metered exactly like chat, and sit under the same model allow-lists and audit log. Video
- Gemini 3 Pro ImageImage generationGemini 3 Pro ImageGeneration models are metered exactly like chat, and sit under the same model allow-lists and audit log. Image
- Eleven Music v2Video generationEleven Music v2Generation models are metered exactly like chat, and sit under the same model allow-lists and audit log. Music
- Eleven v3 Speech
- ElevenLabs Scribe v2 Transcription
Checked against the live model picker on 29 Sept 2026. Models are added as providers ship them and retired when they are deprecated. For context windows and prices, see the model inventory: 343 models across the market, synced 29 Sept 2026, with the ones in StickyPrompts marked.
Pick the model, or let it pick the best one.
Nobody wants to keep a mental table of which model is strongest at what this month. Pick one yourself, or switch on auto select and choose what matters: best quality, a balance, or speed. Try it: change the model and watch the same Northwind question come back in a different voice.
- Switch model mid-conversation without losing the thread
- Auto select for best quality, balanced or fastest
- Every answer shows the model that wrote it
Three changes versus Q2 worth the board's time:
1. Like-for-like sales +6%, with knitwear doing most of the work.
2. Gross margin down 1.5 points: markdowns ran two weeks longer.
3. Click-and-collect is now 22% of online orders, up from 15%.
Every model, what it is good at, what it costs.
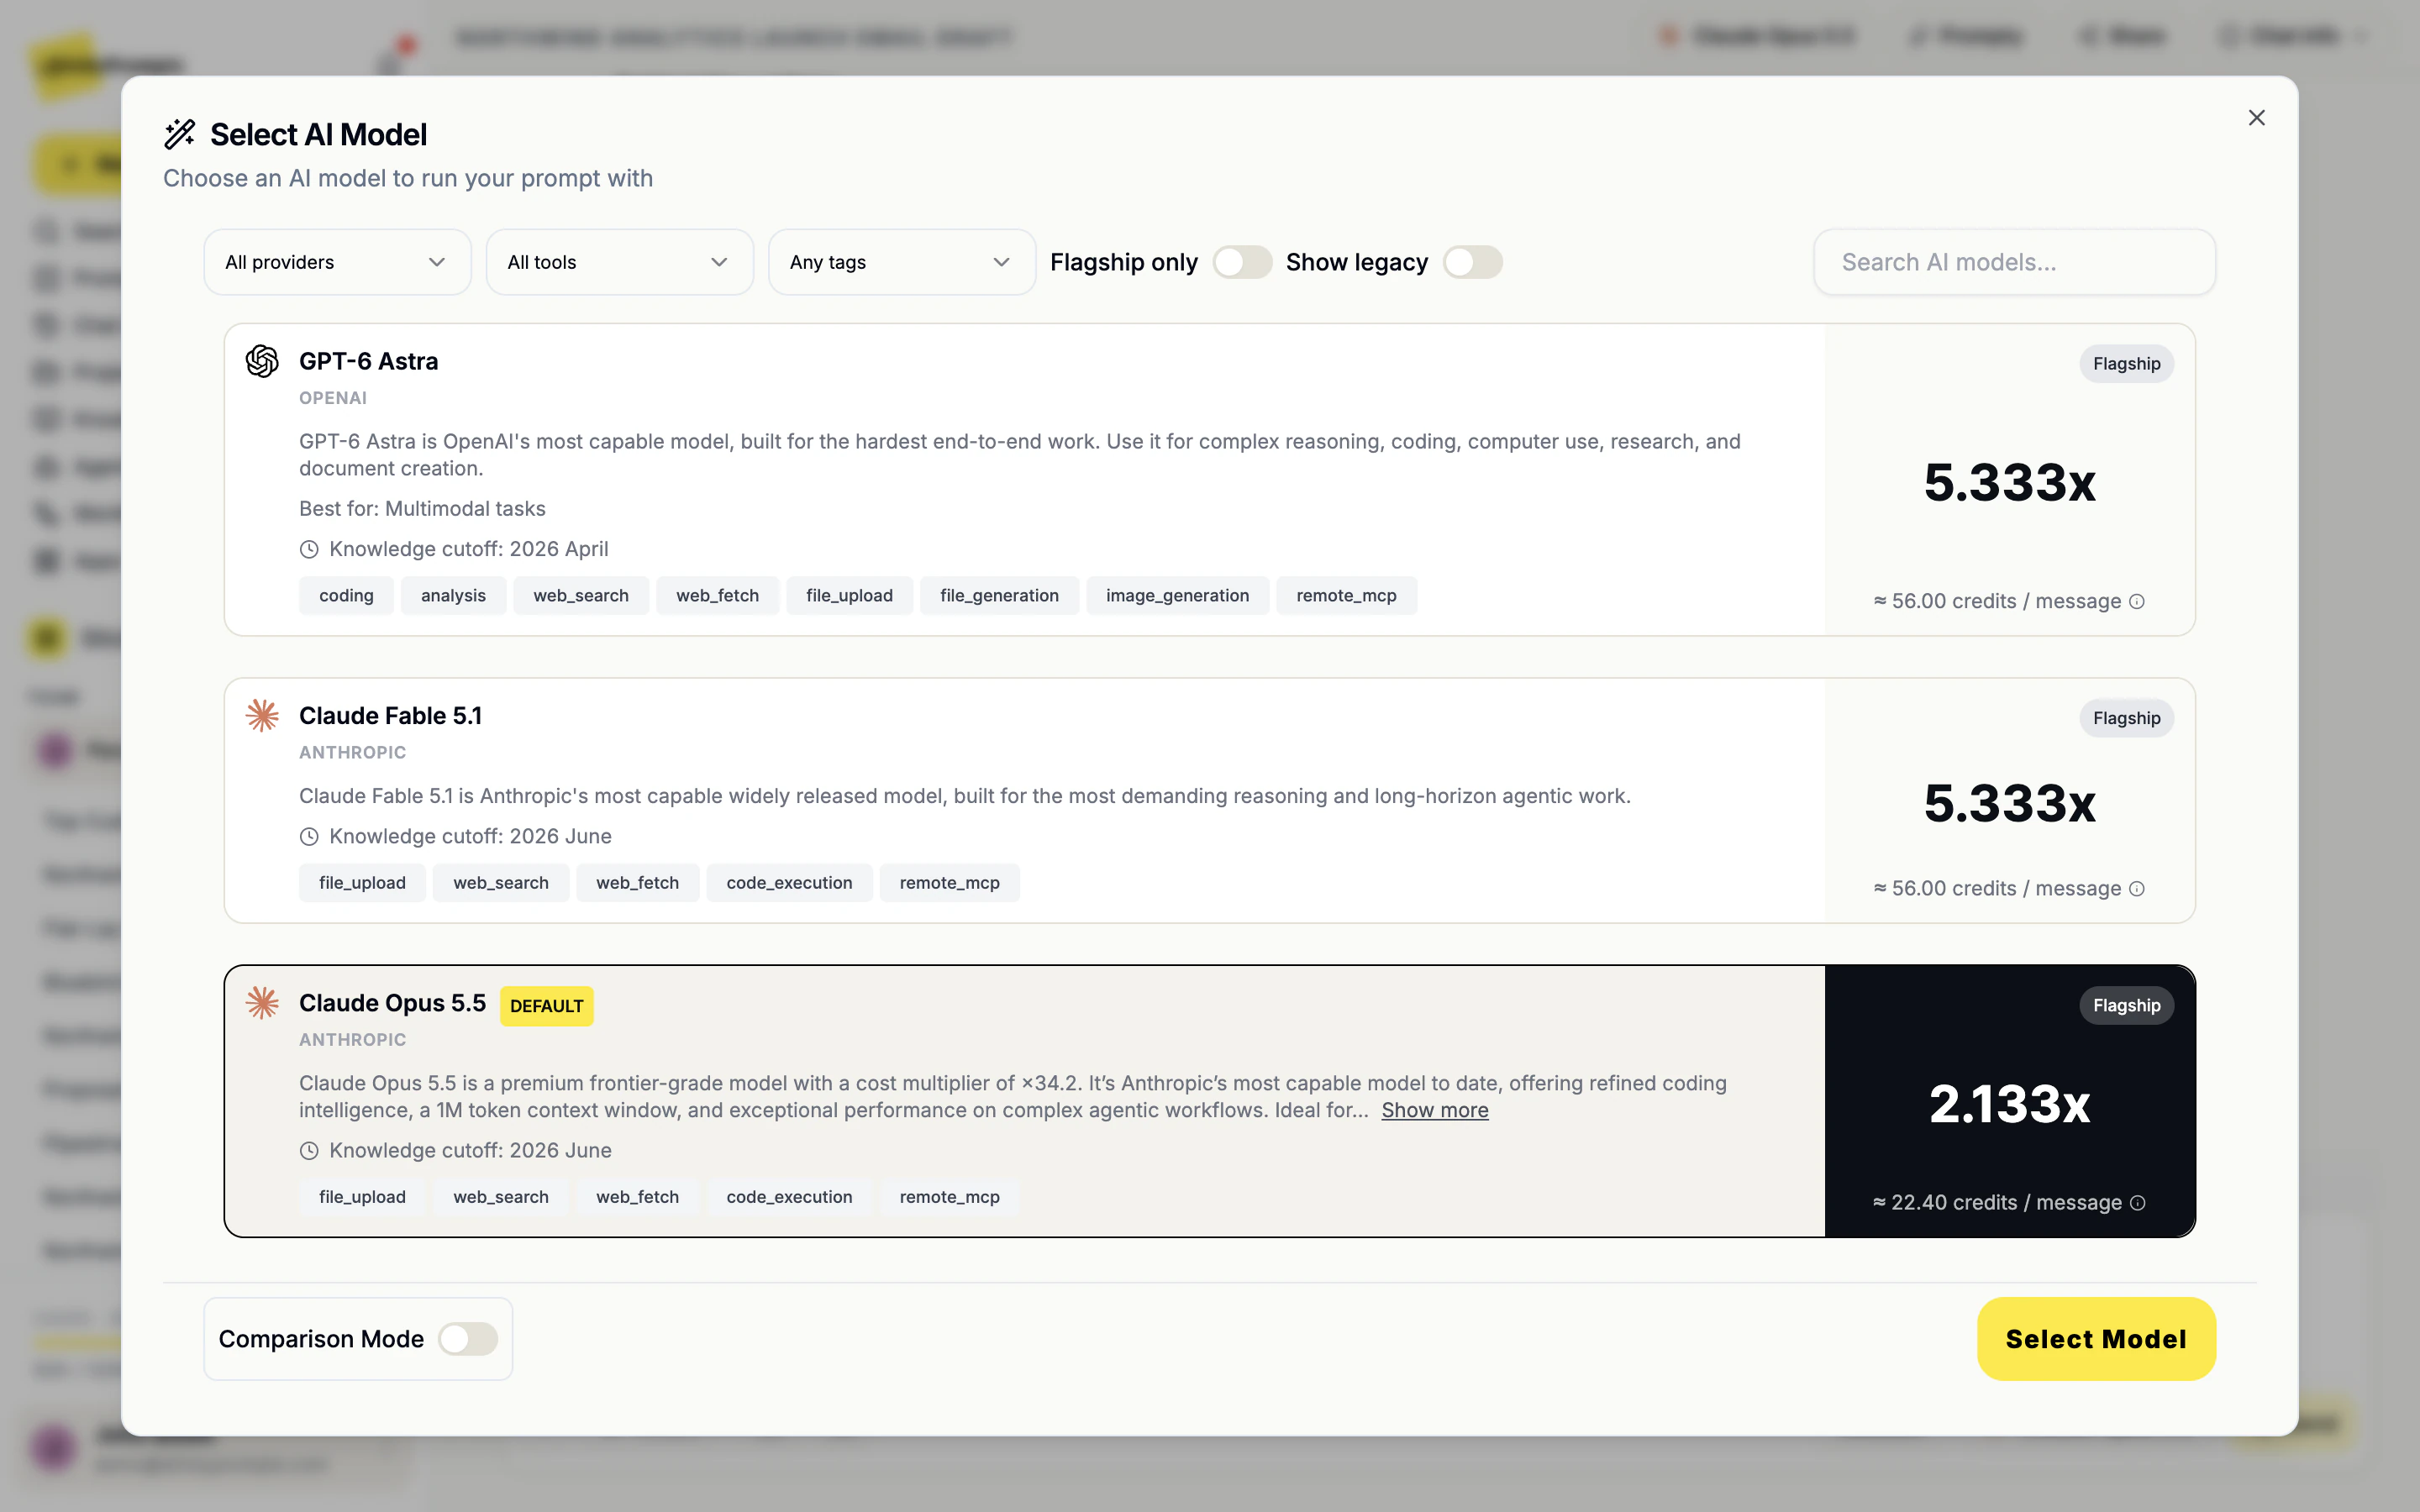
The model selector shows each model's maker, what it is best at, its knowledge cutoff, what it can do (web search, files, code, remote MCP) and what a message costs. Filter by provider or capability, or switch on comparison mode.
- Filter by provider, tool and tag
- The cost of a message shown before you send
- Comparison mode one toggle away
Not sure which one? Ask three at once.
Send one prompt to two to five models and read the answers side by side, with how long each took and what it cost. Then carry on with the one you liked best.
- Two to five models per comparison
- Speed and cost for every answer
- Download the comparison as DOCX
Your rules for where every request goes.
The model list is half the question. The other half is where the request is processed, what the provider may keep, and whose contract it runs under.
- Through StickyPrompts, the default: usage metered at the provider's rate plus your plan's commission
- Bring your own keys: calls billed to your own provider account, from the Business plan up
- Bring your own model: connect one you host yourself and use it beside the rest, under the same policies
- Require EU-served inference or zero data retention, and see which models drop out before you save
Origin is not the same as location
An open-weight model published by a lab in one jurisdiction can be served from an endpoint in another. Require EU-served inference in Data Residency and StickyPrompts only uses EU-hosted endpoints, including for open-weight models, and greys out any model that cannot meet the requirement.
EU AI Act resourcesWhat teams ask about models.
How quickly do new models appear?
Usually soon after a provider releases them. Your prompt library, knowledge bases, agents and policies do not change when a model is added, so trying a new one is a choice in the model picker rather than a project.
What does auto select do?
Instead of naming a model, you can let StickyPrompts choose one for you, tuned for best quality, a balance of quality and speed, or the fastest answer. You can switch to a specific model at any point, and every answer shows which model wrote it.
Can we stop people using a particular model or provider?
Yes. In Model & Provider Access, admins allow or block each provider, or limit it to specific teams. Admins can always use every model. If you require EU-served inference or zero data retention, models that cannot meet it are greyed out automatically.
Do our prompts train anyone's model?
You decide how strict to be. Turn on Zero data retention only in Data Residency and StickyPrompts restricts the catalogue to providers that contractually do not keep your data, and shows you which models drop out before you save.
Can we use our own provider contracts?
Yes. Bring your own keys from the Business plan upwards, and those calls are billed to your account with the provider. You can also connect a model you host yourself. See the pricing page for the plans and the enterprise deployment options.
Give your teams every model and keep your options open.
Start free with a $5 trial balance. When a better model ships, your people switch in the picker. Their prompts, files and habits stay where they are.